Advancing Science Internationally Through Collaboration
Sophie Dorros
March 27, 2026
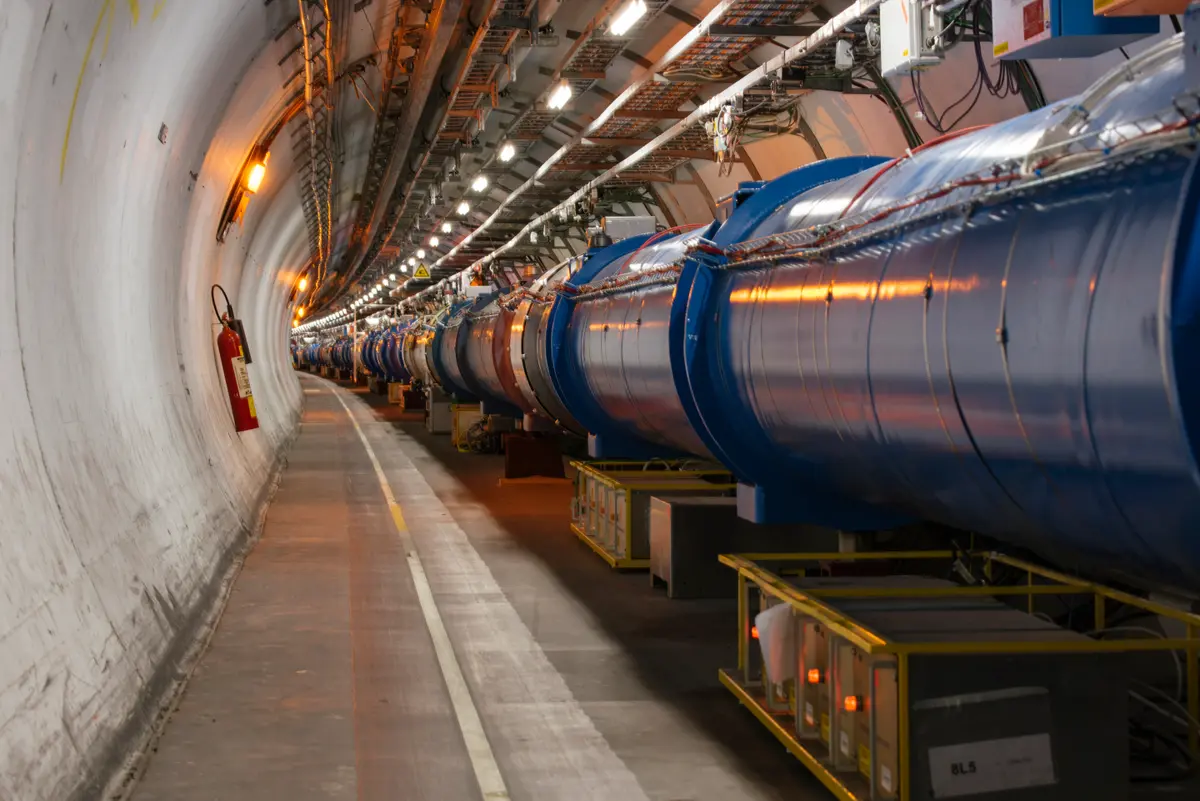
The Large Hadron Collider (LHC)
is the world's largest and most powerful particle accelerator, with two
high-energy particle beams traveling at close to the speed of light before
they are made to collide. But how do particle collisions go from data plots
to groundbreaking scientific advancements, like confirming the existence of
the Higgs-Boson Particle?
Turning collision data into scientific discovery requires collaboration between the Partnership to Advance Throughput Computing (PATh),
an NSF-funded
project designed to accelerate research by advancing
High Throughput Computing (HTC) technologies and services, HTCondor, a high throughput software application developed by
PATh partner the Center for High Throughput Computing (CHTC), and an interconnected
computing grid of over 140 computing centers in more than 40 countries, known as the Worldwide LHC Computing Grid,
or the WLCG.
The WLCG is a global network of data centers that use HTCondor to share computing
power and storage to process and analyze the massive amounts of data produced by
CERN’s Large Hadron Collider. The computing is spread over grid infrastructures
that make up the WLCG, which is then organized into tiers, whose sites receive
data and compute work. Tier-0 at CERN does initial data processing, Tier-1 centers
store and reprocess large datasets, and Tier-2/3 sites, typically clusters at
universities, handle simulation and user analysis. These tiers integrate computer
centres worldwide that provide computing and storage resources through a single
grid accessible by all LHC physicists, regardless of geographic location.
The Foundations of a Partnership
Since its first run in 2010, the LHC has steadily evolved in capability and produced
increasingly large datasets, and CERN began hitting scaling limits with the workload
management system they had in place. They needed a system that would be able to scale
out as the LHC advanced, and wasn't in danger of becoming a proprietary product. After
testing multiple other systems, HTCondor’s flexibility, active community, open source
software, and promising test results made it an ideal choice for the WLCG, and they
began making the switch in 2015. Ben Jones, leader of the Compute and Configuration
section in the IT Department for CERN, emphasized how important this flexibility is:
“The value for us is having something that is tailored to our use case, where the developers
understand and value our use case, and we have something that matches the design
philosophy of the product.”
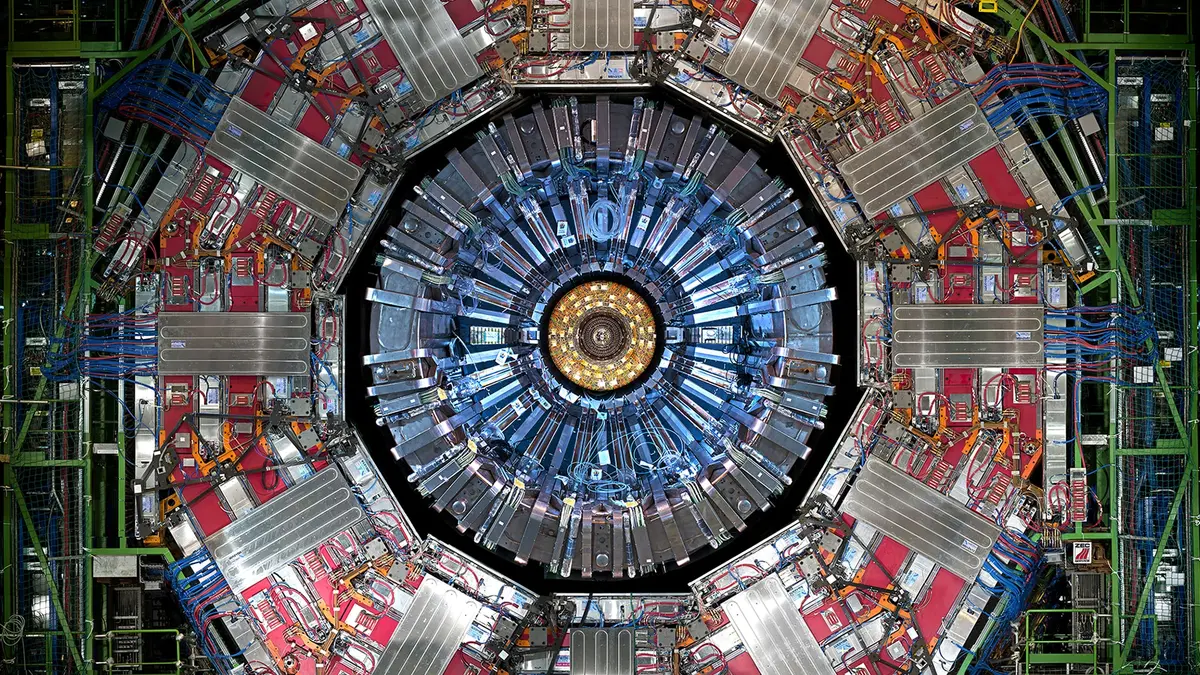
The LHC and its four primary experiments produce over 200 petabytes of data every
year that need to be distributed, stored, and analyzed. The largest of these
experiments, ATLAS and CMS,
use general-purpose detectors to investigate the biggest range of physics possible.
Having two separately designed detectors is essential so scientists can
cross-confirm any new discoveries made. Over the last year, the CMS pool alone has
completed over 500 million jobs using over 3.3 billion CPU hours and over 46 thousand
GPU hours, and transferred over 24 million GB of data using HTCondor.
Todd Tannenbaum, HTCondor Software Lead, reflected on the aspects of HTCondor’s design
that make it particularly well-suited for a multi-site computing environment like the
WLCG’s. Tannenbaum noted: “HTCondor doesn't have scheduling policies baked into it.
It has mechanisms but there's no baked-in rules. So an organization like WLCG can come
up with whatever local policy they want and use the HTCondor ‘recipes’ to enforce it.”
The WLCG relies on a system of underlying grid infrastructures to process data, with the
PATh as the second-largest, delivering up to 35% of pledged storage and computing resources.
Maarten Litmaath, WLCG operations expert and Operations Coordination Co-Chair, stressed the
“Reliance of the whole of the WLCG on crucial middleware … HTCondor has been the computing
workflow engine from the earliest days of WLCG and is nowadays being used at the majority
of our sites to manage the vast majority of the computing capacity at our steady disposal."
A Mutually Beneficial Relationship Built on Community and Open Collaboration
At the same time HTCondor helps make computing the massive amounts of data coming out of
CERN easier, the operations of the LHC and the WLCG are simultaneously making HTCondor
better too. One of the biggest challenges the HTCondor developers face when working with
a system as large as the WLCG is scalability. As the LHC becomes more technologically
advanced, it requires more compute power to process more data. Currently, the WLCG has
around 380,000 running CPU cores and 125,000 running jobs. At the beginnings of the
partnership, that number was closer to 50,000 running CPU cores.
Todd Tannenbaum, reflecting on the massive scalability increases, notes that “The WLCG
often pushes the frontiers of scalability and interoperability.” Scaling up HTCondor
is a tremendous process; it requires coordination between multiple institutions across
the globe, and upgrading all the software of a distributed system running at hundreds
of independent institutions can literally take years, according to Tannenbaum. However,
this work is not without reward: “HTCondor is significantly better than it was. More
scalable, better able to deal with failures than before we started working with the WLCG.”
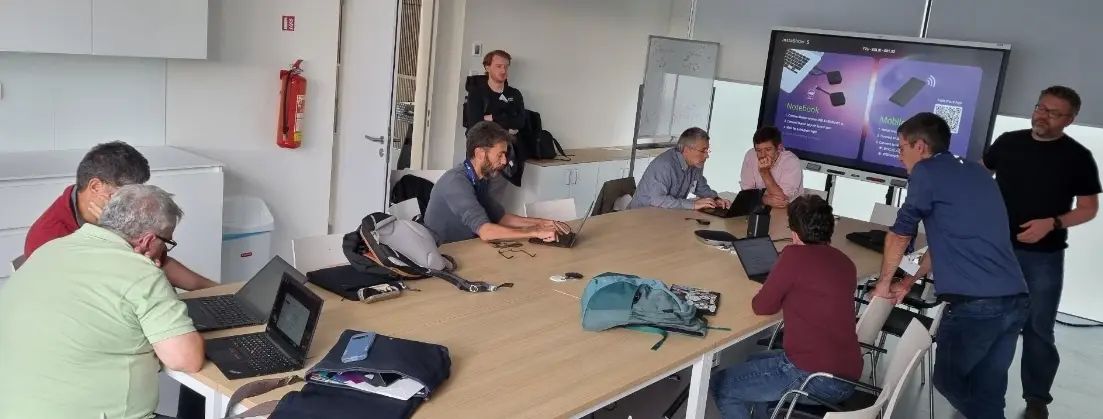
At the center of this multi-national distributed computing partnership is community.
Regular communication between developers, CHTC staff, and CERN is essential to
keep operations running smoothly. Throughput Computing Week in
Madison, the European HTCondor Workshops, and direct
communication with HTCondor developers help computing experts at CERN like Ben Jones solidify the basis
of this large scale compute collaboration. “Like any open source project, it's a two way street. It's not
a business relationship, it's a collaborative relationship,” remarks Jones. Sharing a similar view
Tannenbaum stresses that “Because we're closely collaborating, we're able to see what problems
they're having. We're able to work with them to solve the problems, and that helps clear the path for
the next people.” Both Tannenbaum and Jones emphasize the importance of developer-user communication,
whether that’s quick troubleshooting over email or a more involved meeting. At the same time that
the LHC and the WLCG are pushing the bounds of high energy physics, HTCondor is pushing its own
limits, and reaching new capabilities as a result.
Looking Ahead: A Long Shutdown, the New HL-LHC, and Continued Scaling Challenges
The Long Shutdown 3 (LS3), the
scheduled maintenance for the LHC, is set to begin in July 2026 to prepare for “Run 4”
or the fourth cycle of the LHC. LS3 will transform the LHC into the High-Luminosity LHC (HL-LHC),
creating more particle collisions per second and increasing the amount of data able to
be collected. Currently, there are 125,000 running jobs at a time, and the HL-LHC will
require that capacity to more than triple. “So as the LHC is increasing in its luminosity
and the amount of things it needs to do, the technology can never be a limiting factor.
So being able to scale and have the developers scale the system way beyond what it was
originally doing is the thing that's really enabled us to meet the challenges for the LHC,
” notes Jones. In October 2025, The CERN IT team carried out a stress test
on its computing infrastructure, and
injected 16,800 additional jobs into the system, around 20 times the current average
throughput. HTCondor withstood the test, and the average job
handling time remained at a reasonable 5 minutes for the scale of jobs.
Another challenge in the progression of the partnership comes from the heterogeneous
computing environment. CPU cores are not coordinating in a controlled data center
environment, and networking capacity and speed vary drastically between locations within
the WLCG. HTCondor has had to adapt to shift across networking standards and addressing
while scaling rapidly at the same time. As CERN and the WLCG prepare for the upcoming shutdown,
HTCondor is preparing to make continued increases in scale. Because the WLCG is a global
computing grid, it’s not possible to set a universal upgrade date or time. Tannenbaum
reflected on this continued challenge in coordination: “Keeping things intercompatible
across versions spanning years, has been a challenge.” As the needs of the LHC advance,
HTCondor must find ways to work around the global coordination challenges.